Note
Go to the end to download the full example code.
Fused Softmax
In this tutorial, you will write a fused softmax operation that is significantly faster than PyTorch’s native op for a particular class of matrices: those whose rows can fit in the GPU’s SRAM.
In doing so, you will learn about:
The benefits of kernel fusion for bandwidth-bound operations.
Reduction operators in Triton.
Motivations
Custom GPU kernels for elementwise additions are educationally valuable but won’t get you very far in practice. Let us consider instead the case of a simple (numerically stabilized) softmax operation:
import torch

import triton
import triton.language as tl
from triton.runtime import driver

DEVICE = triton.runtime.driver.active.get_active_torch_device()


def is_hip():
    return triton.runtime.driver.active.get_current_target().backend == "hip"


def is_cdna():
    return is_hip() and triton.runtime.driver.active.get_current_target().arch in ('gfx940', 'gfx941', 'gfx942',
                                                                                   'gfx90a')


def naive_softmax(x):
    """Compute row-wise softmax of X using native pytorch

    We subtract the maximum element in order to avoid overflows. Softmax is invariant to
    this shift.
    """
    # read  MN elements ; write M  elements
    x_max = x.max(dim=1)[0]
    # read MN + M elements ; write MN elements
    z = x - x_max[:, None]
    # read  MN elements ; write MN elements
    numerator = torch.exp(z)
    # read  MN elements ; write M  elements
    denominator = numerator.sum(dim=1)
    # read MN + M elements ; write MN elements
    ret = numerator / denominator[:, None]
    # in total: read 5MN + 2M elements ; wrote 3MN + 2M elements
    return ret
When implemented naively in PyTorch, computing y = naive_softmax(x) for \(x \in R^{M \times N}\)
requires reading \(5MN + 2M\) elements from DRAM and writing back \(3MN + 2M\) elements.
This is obviously wasteful; we’d prefer to have a custom “fused” kernel that only reads
X once and does all the necessary computations on-chip.
Doing so would require reading and writing back only \(MN\) bytes, so we could
expect a theoretical speed-up of ~4x (i.e., \((8MN + 4M) / 2MN\)).
The torch.jit.script flags aims to perform this kind of “kernel fusion” automatically
but, as we will see later, it is still far from ideal.
Compute Kernel
Our softmax kernel works as follows: each program loads a set of rows of the input matrix X strided by number of programs, normalizes it and writes back the result to the output Y.
Note that one important limitation of Triton is that each block must have a power-of-two number of elements, so we need to internally “pad” each row and guard the memory operations properly if we want to handle any possible input shapes:
@triton.jit
def softmax_kernel(output_ptr, input_ptr, input_row_stride, output_row_stride, n_rows, n_cols, BLOCK_SIZE: tl.constexpr,
                   num_stages: tl.constexpr):
    # starting row of the program
    row_start = tl.program_id(0)
    row_step = tl.num_programs(0)
    for row_idx in tl.range(row_start, n_rows, row_step, num_stages=num_stages):
        # The stride represents how much we need to increase the pointer to advance 1 row
        row_start_ptr = input_ptr + row_idx * input_row_stride
        # The block size is the next power of two greater than n_cols, so we can fit each
        # row in a single block
        col_offsets = tl.arange(0, BLOCK_SIZE)
        input_ptrs = row_start_ptr + col_offsets
        # Load the row into SRAM, using a mask since BLOCK_SIZE may be > than n_cols
        mask = col_offsets < n_cols
        row = tl.load(input_ptrs, mask=mask, other=-float('inf'))
        # Subtract maximum for numerical stability
        row_minus_max = row - tl.max(row, axis=0)
        # Note that exponentiation in Triton is fast but approximate (i.e., think __expf in CUDA)
        numerator = tl.exp(row_minus_max)
        denominator = tl.sum(numerator, axis=0)
        softmax_output = numerator / denominator
        # Write back output to DRAM
        output_row_start_ptr = output_ptr + row_idx * output_row_stride
        output_ptrs = output_row_start_ptr + col_offsets
        tl.store(output_ptrs, softmax_output, mask=mask)
We can create a helper function that enqueues the kernel and its (meta-)arguments for any given input tensor.
properties = driver.active.utils.get_device_properties(DEVICE.index)
NUM_SM = properties["multiprocessor_count"]
NUM_REGS = properties["max_num_regs"]
SIZE_SMEM = properties["max_shared_mem"]
WARP_SIZE = properties["warpSize"]
target = triton.runtime.driver.active.get_current_target()
kernels = {}


def softmax(x):
    n_rows, n_cols = x.shape

    # The block size of each loop iteration is the smallest power of two greater than the number of columns in `x`
    BLOCK_SIZE = triton.next_power_of_2(n_cols)

    # Another trick we can use is to ask the compiler to use more threads per row by
    # increasing the number of warps (`num_warps`) over which each row is distributed.
    # You will see in the next tutorial how to auto-tune this value in a more natural
    # way so you don't have to come up with manual heuristics yourself.
    num_warps = 8

    # Number of software pipelining stages.
    num_stages = 4 if SIZE_SMEM > 200000 else 2

    # Allocate output
    y = torch.empty_like(x)

    # pre-compile kernel to get register usage and compute thread occupancy.
    kernel = softmax_kernel.warmup(y, x, x.stride(0), y.stride(0), n_rows, n_cols, BLOCK_SIZE=BLOCK_SIZE,
                                   num_stages=num_stages, num_warps=num_warps, grid=(1, ))
    kernel._init_handles()
    n_regs = kernel.n_regs
    size_smem = kernel.metadata.shared
    if is_hip():
        # NUM_REGS represents the number of regular purpose registers. On CDNA architectures this is half of all registers available.
        # However, this is not always the case. In most cases all registers can be used as regular purpose registers.
        # ISA SECTION (3.6.4 for CDNA3)
        # VGPRs are allocated out of two pools: regular VGPRs and accumulation VGPRs. Accumulation VGPRs are used
        # with matrix VALU instructions, and can also be loaded directly from memory. A wave may have up to 512 total
        # VGPRs, 256 of each type. When a wave has fewer than 512 total VGPRs, the number of each type is flexible - it is
        # not required to be equal numbers of both types.
        NUM_GPRS = NUM_REGS
        if is_cdna():
            NUM_GPRS = NUM_REGS * 2

        # MAX_NUM_THREADS represents maximum number of resident threads per multi-processor.
        # When we divide this number with WARP_SIZE we get maximum number of waves that can
        # execute on a CU (multi-processor)  in parallel.
        MAX_NUM_THREADS = properties["max_threads_per_sm"]
        max_num_waves = MAX_NUM_THREADS // WARP_SIZE
        occupancy = min(NUM_GPRS // WARP_SIZE // n_regs, max_num_waves) // num_warps
    else:
        occupancy = NUM_REGS // (n_regs * WARP_SIZE * num_warps)
    occupancy = min(occupancy, SIZE_SMEM // size_smem)
    num_programs = NUM_SM * occupancy

    num_programs = min(num_programs, n_rows)

    # Create a number of persistent programs.
    kernel[(num_programs, 1, 1)](y, x, x.stride(0), y.stride(0), n_rows, n_cols, BLOCK_SIZE, num_stages)
    return y
Unit Test
We make sure that we test our kernel on a matrix with an irregular number of rows and columns. This will allow us to verify that our padding mechanism works.
torch.manual_seed(0)
x = torch.randn(1823, 781, device=DEVICE)
y_triton = softmax(x)
y_torch = torch.softmax(x, axis=1)
assert torch.allclose(y_triton, y_torch), (y_triton, y_torch)
As expected, the results are identical.
Benchmark
Here we will benchmark our operation as a function of the number of columns in the input matrix – assuming 4096 rows.
We will then compare its performance against (1) torch.softmax and (2) the naive_softmax defined above.
@triton.testing.perf_report(
    triton.testing.Benchmark(
        x_names=['N'],  # argument names to use as an x-axis for the plot
        x_vals=[128 * i for i in range(2, 100)],  # different possible values for `x_name`
        line_arg='provider',  # argument name whose value corresponds to a different line in the plot
        line_vals=['triton', 'torch', 'naive_softmax'],  # possible values for `line_arg``
        line_names=["Triton", "Torch", "Naive Softmax"],  # label name for the lines
        styles=[('blue', '-'), ('green', '-'), ('red', '-')],  # line styles
        ylabel="GB/s",  # label name for the y-axis
        plot_name="softmax-performance",  # name for the plot. Used also as a file name for saving the plot.
        args={'M': 4096},  # values for function arguments not in `x_names` and `y_name`
    ))
def benchmark(M, N, provider):
    x = torch.randn(M, N, device=DEVICE, dtype=torch.float32)
    if provider == 'torch':
        ms = triton.testing.do_bench(lambda: torch.softmax(x, axis=-1))
    if provider == 'triton':
        ms = triton.testing.do_bench(lambda: softmax(x))
    if provider == 'naive_softmax':
        ms = triton.testing.do_bench(lambda: naive_softmax(x))
    gbps = lambda ms: 2 * x.numel() * x.element_size() * 1e-9 / (ms * 1e-3)
    return gbps(ms)


benchmark.run(show_plots=True, print_data=True)
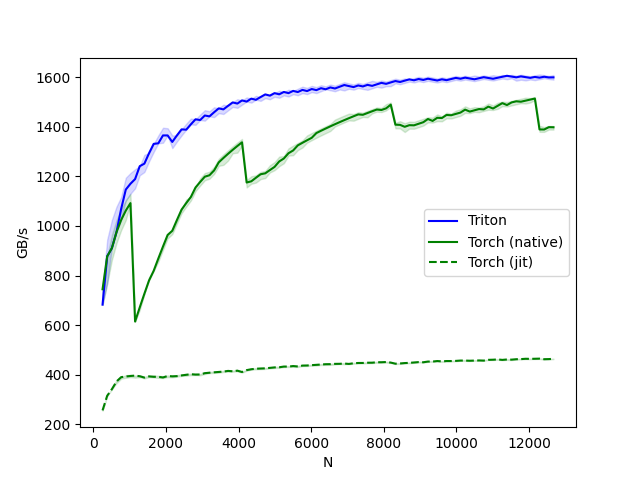
softmax-performance:
          N  Triton (GB/s)  Torch (GB/s)  Naive Softmax (GB/s)
0     256.0     499.094191    689.077529            206.136795
1     384.0     692.248625    787.411436            261.340281
2     512.0     834.667138    928.641557            301.065783
3     640.0     821.930080    915.229125            330.828675
4     768.0     903.225936    973.574690            347.586297
5     896.0     970.034017   1030.973073            357.331241
6    1024.0    1032.679450   1067.523594            352.525881
7    1152.0    1116.339156   1067.406527            350.270645
8    1280.0    1142.344318   1105.524715            349.133111
9    1408.0    1178.726669   1143.124723            340.819839
10   1536.0    1192.136206   1158.614692            336.569386
11   1664.0    1230.476691   1188.961546            329.248525
12   1792.0    1244.406738   1198.488870            327.370248
13   1920.0    1273.056238   1215.339293            324.584524
14   2048.0    1283.418670   1247.827500            326.454367
15   2176.0    1254.065723    962.828342            326.228848
16   2304.0    1260.218659   1001.614291            326.305795
17   2432.0    1291.250231   1039.458394            328.333574
18   2560.0    1301.232543   1072.625739            329.059416
19   2688.0    1309.448966   1101.655906            331.109680
20   2816.0    1320.971672   1123.223490            329.776011
21   2944.0    1336.283650   1150.232421            330.386602
22   3072.0    1341.871975   1171.161177            334.136969
23   3200.0    1350.715727   1171.983551            335.147959
24   3328.0    1360.862834   1203.553597            336.284790
25   3456.0    1371.586206   1227.367889            337.026083
26   3584.0    1379.386903   1248.337397            338.516372
27   3712.0    1385.074628   1265.887640            340.232212
28   3840.0    1387.483009   1282.915101            340.241307
29   3968.0    1397.009303   1297.373256            341.658919
30   4096.0    1401.489669   1313.865448            338.367228
31   4224.0    1354.981504   1280.222681            343.383787
32   4352.0    1359.919127   1299.752784            345.539335
33   4480.0    1370.914678   1318.260699            346.634245
34   4608.0    1378.459638   1331.048731            347.596200
35   4736.0    1383.462232   1348.195504            348.097096
36   4864.0    1395.574238   1362.487676            349.965026
37   4992.0    1391.935630   1371.036606            350.348990
38   5120.0    1400.598616   1386.822325            351.166169
39   5248.0    1397.050387   1359.204248            352.434162
40   5376.0    1402.570523   1371.493426            352.351112
41   5504.0    1405.659754   1384.906713            354.072952
42   5632.0    1415.870074   1390.748841            353.976640
43   5760.0    1422.668779   1405.425721            355.302851
44   5888.0    1428.164576   1422.083583            355.109117
45   6016.0    1424.110575   1423.959662            356.651503
46   6144.0    1428.855223   1432.495969            357.682773
47   6272.0    1436.329867   1402.632772            358.459867
48   6400.0    1440.552778   1407.802725            358.839976
49   6528.0    1435.977261   1417.912763            359.388661
50   6656.0    1441.335134   1424.866842            360.605185
51   6784.0    1438.980296   1439.017983            360.661601
52   6912.0    1442.340348   1446.965370            361.105309
53   7040.0    1445.670865   1451.271887            361.358507
54   7168.0    1452.089347   1460.821867            362.601648
55   7296.0    1457.270591   1087.547429            363.029684
56   7424.0    1454.507436   1101.409419            363.417795
57   7552.0    1448.974797   1113.677733            364.084318
58   7680.0    1463.220027   1127.131135            363.821655
59   7808.0    1460.120440   1133.484716            365.003769
60   7936.0    1462.397160   1144.955621            365.144926
61   8064.0    1462.328132   1152.191219            365.221197
62   8192.0    1459.039598   1154.684507            364.451728
63   8320.0    1396.199753   1115.908195            362.222413
64   8448.0    1388.149582   1124.021710            362.800707
65   8576.0    1395.235048   1128.964167            363.932420
66   8704.0    1390.694978   1134.866436            364.681433
67   8832.0    1390.457037   1132.678812            365.525983
68   8960.0    1396.347448   1138.399606            366.832787
69   9088.0    1417.799520   1136.491248            367.165172
70   9216.0    1420.745431   1142.013271            368.197628
71   9344.0    1422.595846   1424.220246            367.863366
72   9472.0    1417.551443   1436.962512            369.059722
73   9600.0    1419.133318   1432.217297            369.701783
74   9728.0    1424.306490   1440.664514            370.238759
75   9856.0    1428.517268   1440.616004            370.804581
76   9984.0    1421.305402   1451.994045            371.426437
77  10112.0    1428.087525   1457.635524            372.234240
78  10240.0    1427.501665   1468.715858            372.287933
79  10368.0    1438.616189   1462.286786            370.374609
80  10496.0    1441.415183   1466.220252            370.937709
81  10624.0    1430.841750   1468.495090            371.660104
82  10752.0    1425.351444   1472.072435            371.965499
83  10880.0    1424.119330   1479.063710            372.620462
84  11008.0    1433.286677   1478.760476            373.321392
85  11136.0    1442.230169   1488.673700            374.060358
86  11264.0    1450.811499   1489.797927            373.712650
87  11392.0    1445.157832   1493.664018            374.885672
88  11520.0    1448.569211   1497.485357            374.187543
89  11648.0    1448.797183   1501.137206            374.910480
90  11776.0    1451.809835   1504.612348            375.656418
91  11904.0    1461.322016   1510.346966            375.924617
92  12032.0    1447.527830   1509.024924            376.225760
93  12160.0    1432.426895   1514.548306            376.378225
94  12288.0    1461.538316   1416.661646            376.305475
95  12416.0    1469.177286   1394.699643            375.278459
96  12544.0    1468.258455   1398.828241            376.118723
97  12672.0    1468.125654   1397.839776            376.083777
- In the above plot, we can see that:
Triton is 4x faster than the Torch JIT. This confirms our suspicions that the Torch JIT does not do any fusion here.
Triton is noticeably faster than
torch.softmax– in addition to being easier to read, understand and maintain. Note however that the PyTorch softmax operation is more general and will work on tensors of any shape.
Total running time of the script: (0 minutes 36.842 seconds)